Small-model guidelines
How Ondai designs for 3B-parameter models with a 4,096-token context.
- Budget everything. Assume 4,096 tokens worst case. Every component declares an input budget and a long-input strategy (truncate, map-reduce, last-N messages).
- Fresh session per task. No growing chat history. Summarize if you need memory.
- Strict, shallow schemas with enums. Apple's constrained decoding handles objects, arrays, primitives and enums; keep nesting flat.
- Deterministic helpers beat the model. Dates, money, numbers and enum matching are parsed in code after the model answers (
refineObject). Confidence comes from how much had to be corrected. - Ground everything. Tools return preformatted strings the UI shows verbatim; the model never invents figures about app data.
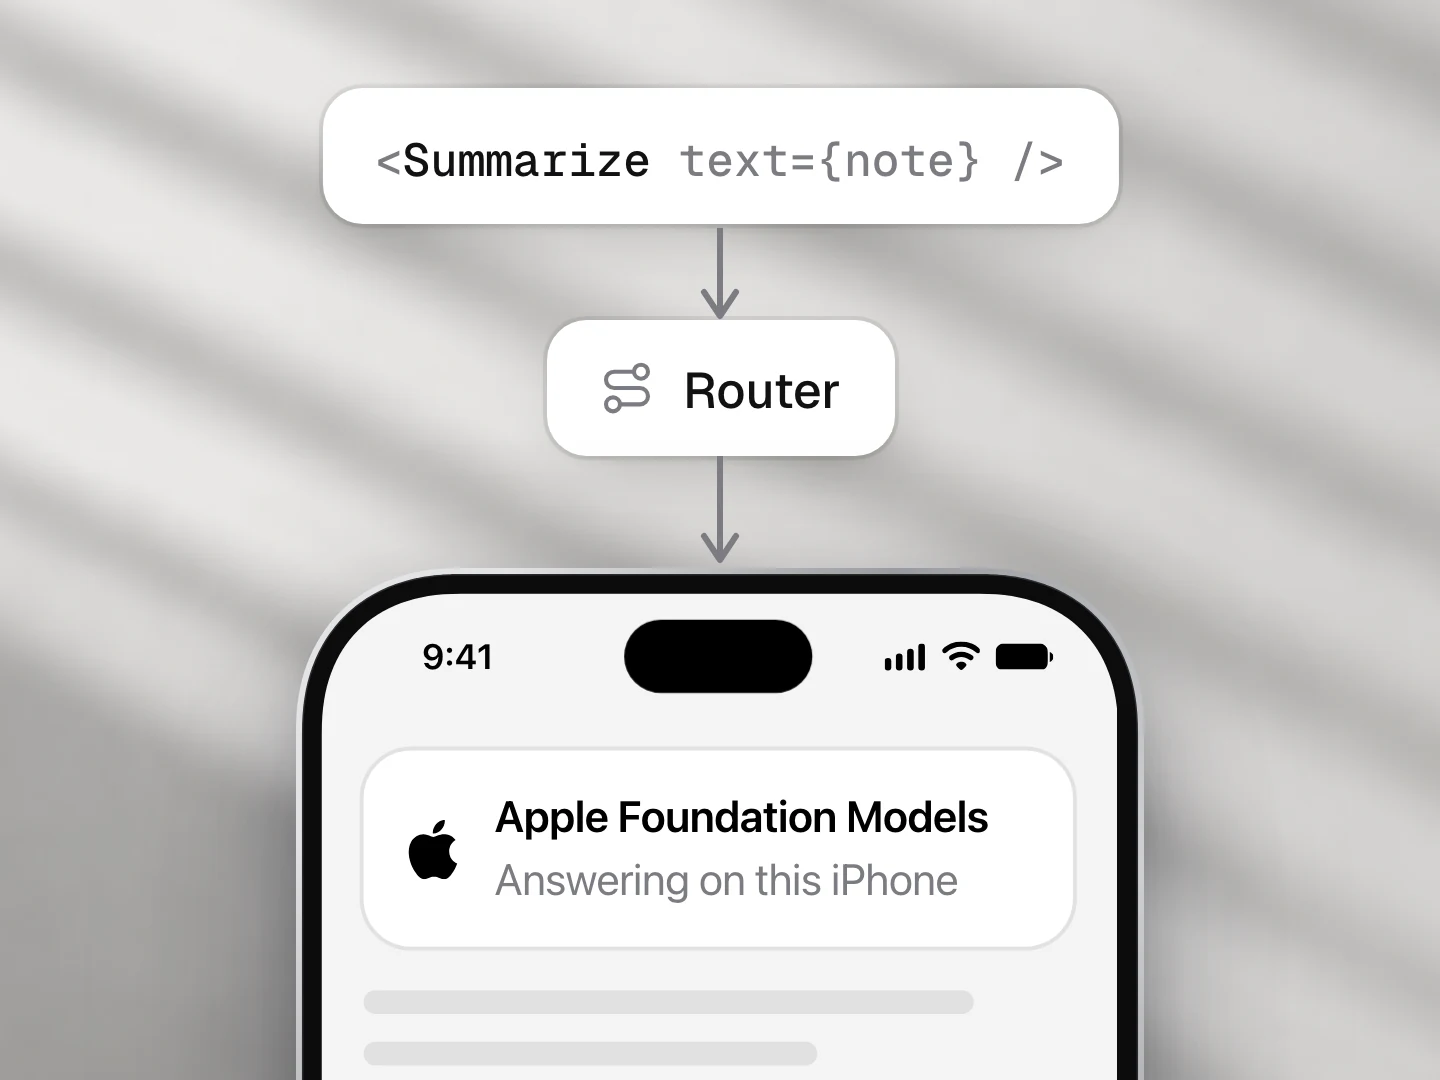
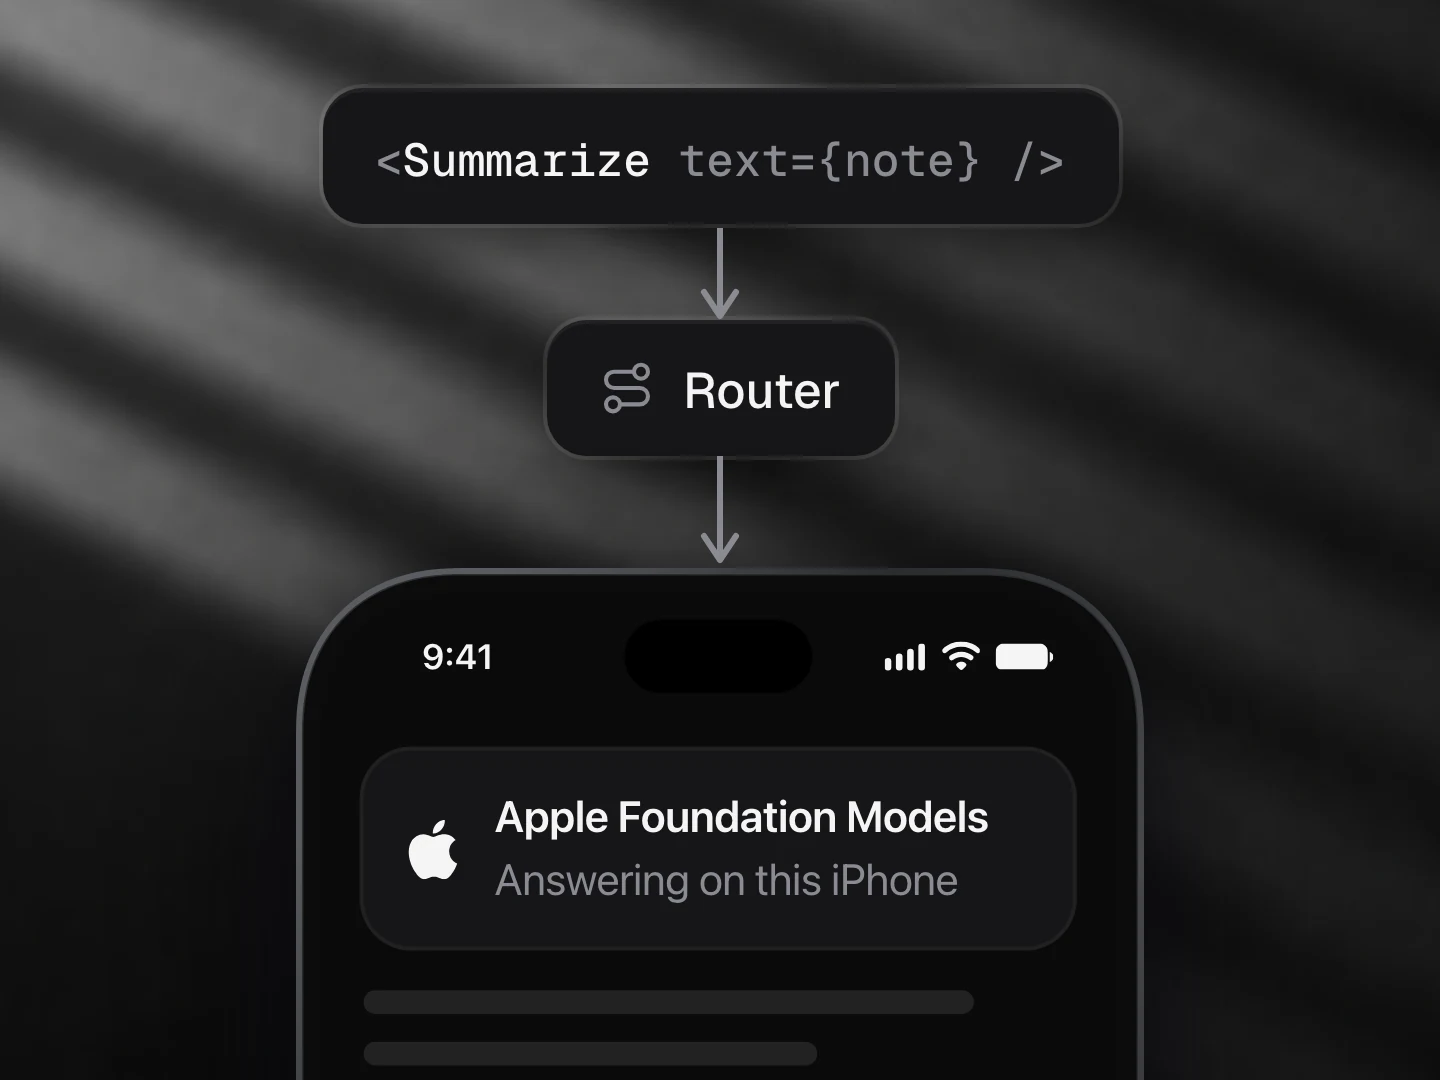
- Preselect tools. With many actions, the top 3–5 by relevance are sent to the model.
- Classify errors, never loop. One retry with a smaller budget on context overflow or invalid output; refusals and quota errors get calm UI, not retries.
- Prewarm. First token on a cold session is ~1 s on Apple; warm the model on focus.
- Treat content as data. Tool outputs and user content are never instructions. Tool policy (
auto | ask | never) lives in core.